AI-Powered Virtual Chat Assistant for Public Census & Demographic Data
Public census data was scattered across thousands of files. We built an AI assistant that lets citizens and officials ask questions in text or voice and get accurate answers in seconds.
The impact
90% faster queries
Response time to citizen and media queries fell by over 90%, analysts' manual effort dropped and public access to demographic data improved.
At a glance
The project in four answers
What was the problem?
Decades of census data sat in thousands of PDFs, Excel sheets and text files, so even simple questions took analysts hours to answer.
What did Kreeda Labs build?
An AI chat assistant that answers census questions in text or voice, using orchestrated large language models over a vector database of official documents.
Which technologies were used?
Large language models, a vector database, PDF and Excel ingestion pipelines, speech-to-text and text-to-speech, and a Next.js interface on serverless infrastructure.
What was the outcome?
Response time to citizen and media queries fell by over 90%, analysts' manual effort dropped and public access to demographic data improved.
Project overview
Government census data answers critical questions about population, education, housing, and access to basic services. But these answers were buried inside thousands of PDFs, Excel files, and static reports spread across years and regions. Even trained analysts had to manually search, cross-check, and validate multiple datasets to respond to a single query.
For citizens, journalists, and policymakers, the challenge was bigger. The data was public, but accessing it, understanding it, or comparing it across time and geography was slow and impractical.
What was missing wasn't data. It was a way to ask questions and get clear answers. This project solved that by turning decades of census information into an AI-powered system that allows people to ask questions using text or voice and receive accurate, official responses within seconds.
The challenge
When Data Exists, But Answers Don't
Massive, Fragmented Data at Scale
Decades of census data across population, housing, education, and infrastructure lived in PDFs, Excel sheets, and text files with no consistent structure.
Slow, Manual Data Retrieval
Answering even basic questions required analysts to search for multiple documents, verify numbers, and cross-check years, wasting time and public resources.
Low Public Accessibility and Usability
Citizens struggled to find, interpret, compare, or understand complex tables, regional data, and historical trends despite information being publicly available.
No Unified, Conversational Access Layer
There was no centralized system to query data across national to local levels, nor support for voice-based access needed for diverse users and digital literacy levels.
What Kreeda Labs built
An AI Chat Assistant for Census Data
AI-Powered Statistical Chat Assistant
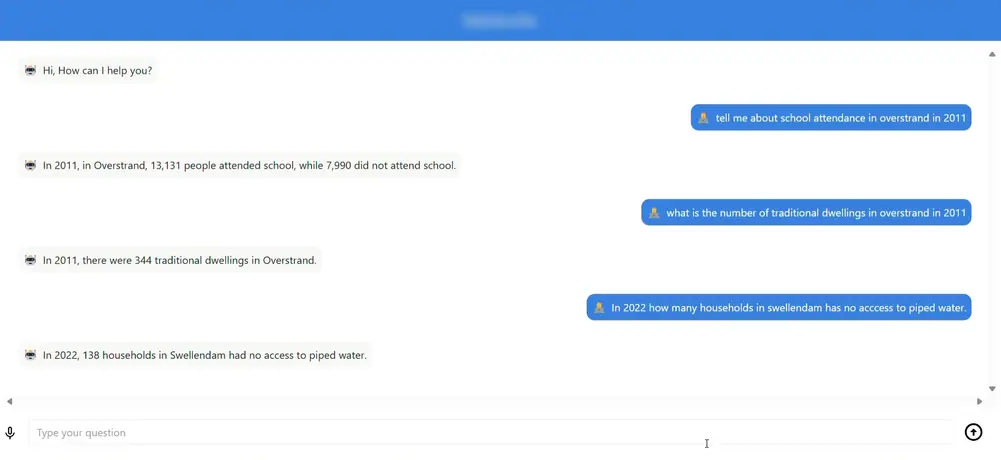
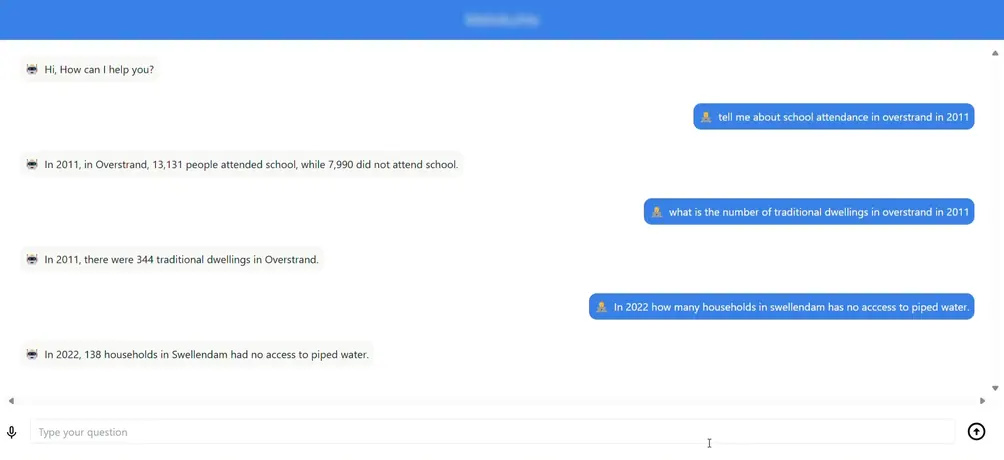
A smart, interactive chatbot capable of understanding natural language questions and delivering clear, accurate outputs from official census data. Interprets complex questions. Identifies location, time period, and metric. Responds with structured, validated information.
Advanced LLM Orchestration
Multiple large language models were orchestrated to handle: Query understanding. Context retention. Data retrieval from vector databases. Large document reasoning. This created a stable, intelligent, and scalable system for accurate information retrieval.
Vector Database Knowledge Architecture
All census documents and datasets were indexed in a vector database, enabling: Fast semantic search. High-precision retrieval. Context-driven results rather than keyword-based guessing.
Next.js-Based User Interface
The application was built using Next.js, giving: Complete control over performance. Scalable architecture. Custom design for government accessibility standards. Serverless backend for speed and stability.
Text + Voice-Based Interaction
Users can: Type their question. Speak their question. Receive the answer as text or voice output. This expanded usability across: Mobile users, Low-literacy communities, Visually impaired users, Remote areas.
Multi-Platform Integration Ready
The solution was built to integrate with: Official websites, WhatsApp, Slack, Discord, Instagram, Other government portals. This ensures broader reach and easier adoption.
Product experience
Inside the product
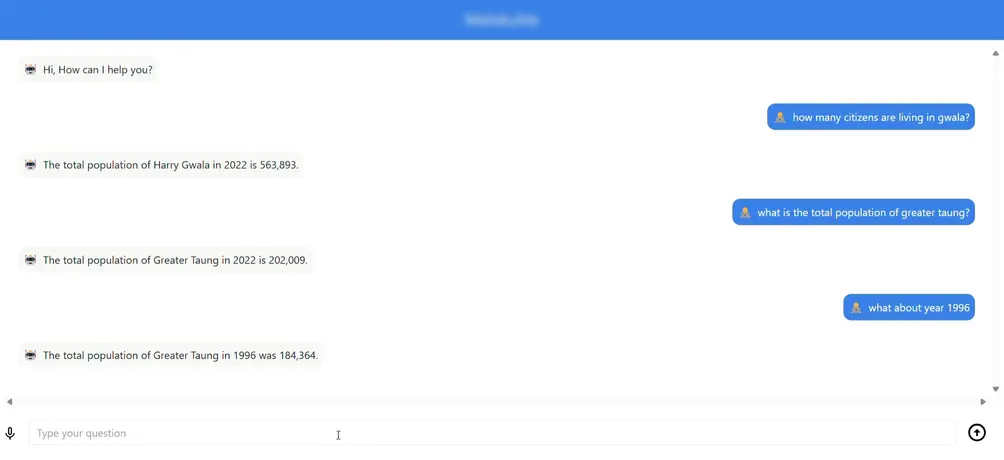
Engineering
How it is built
The stack behind the build, layer by layer.
Frontend
Next.js-based web interface optimized for accessibility
Backend
Serverless architecture for query handling and orchestration
AI & NLP
Large Language Models for query understanding and response generation
Knowledge Retrieval
Vector database for semantic search across census documents
Data Processing
PDF and Excel ingestion pipelines for structured and unstructured data
Voice Processing
Speech-to-text and text-to-speech for voice-based interaction
Infrastructure
Cloud-hosted deployment with scalable compute
Outcome
Results that matter
Results that matter
Reduced response time to citizen and media queries by over 90%
Eliminated heavy manual effort required by analysts
Dramatically increased data accessibility for the public
Improved transparency and engagement between government and citizens
Created a future-ready model for AI-based public services
Established a single source of truth for demographic data
Beyond launch
What comes next
What's next
- New census data can be added easily
- Additional languages can be incorporated
- Deeper analytical features can be introduced
- Can be expanded to other departments and ministries
Start a conversation
Have an idea worth building?
Tell us what you want to build. You’ll hear back from our team, not an automated sequence.
- 01We review your brief
- 02A call with an engineer to scope it
- 03A proposal with timeline and budget breakdown